Entity resolution
A configurable pipeline that cleans, pairs and scores records to find the same person, company or product across datasets, with a labelling app where stewards confirm, flag or reject each match and a config manager that defines every step.
One working session with the people in the seat: which decisions, which systems, what a good week looks like.
The app you see above, running on your own exports instead of the simulated world. Every screen, every decision, your numbers.
Wired to your systems with your permissions, agents proposing, people approving, the ledger recording who did what.
Overview
Customers, suppliers and materials are duplicated across systems, and comparing every row with every other does not scale. Sanctions screening and supplier onboarding both stall on it.
The framework runs three configurable stages: cleaning per column, pairing to shortlist candidates without a full cross join, and comparison that scores each pair. The config manager sets the techniques per step with a live preview; the labelling app shows both records side by side with the score and a predicted label, and every confirm or reject trains the next run. Grouped and bulk review clear the long tail.
Key features
- Match confirmation interface: individual, grouped and bulk review with score, predicted label and the two records' properties side by side.
- Configuration interface: entity resolution requests, cleaning, pairing and comparison steps with a preview and links per step.
- Cleaning, pairing and comparison techniques out of the box (lowercase, trim, company normalisation; Min Hash, sorted neighbourhood; Jaro, normalized Indel), plus custom ones.
- Recommenders for pairing and comparison techniques from the labelled sample.
Decisions it produces
- Confirm, flag or reject a candidate match
- Confirm a cluster as one entity
- Bulk-confirm above a threshold
- Commit a pipeline change and run it
Data sources
| Reference input | customers from CRM, materials or suppliers from ERP, one row per entity |
|---|---|
| Target | the dataset to match against, or the input itself for deduplication |
| Sanctions and watch lists | screening targets with names, addresses, identifiers |
| Steward labels | confirmed and rejected pairs that tune the scoring |
Simulated data throughout. Book a call to see it on your own systems.
Related demos
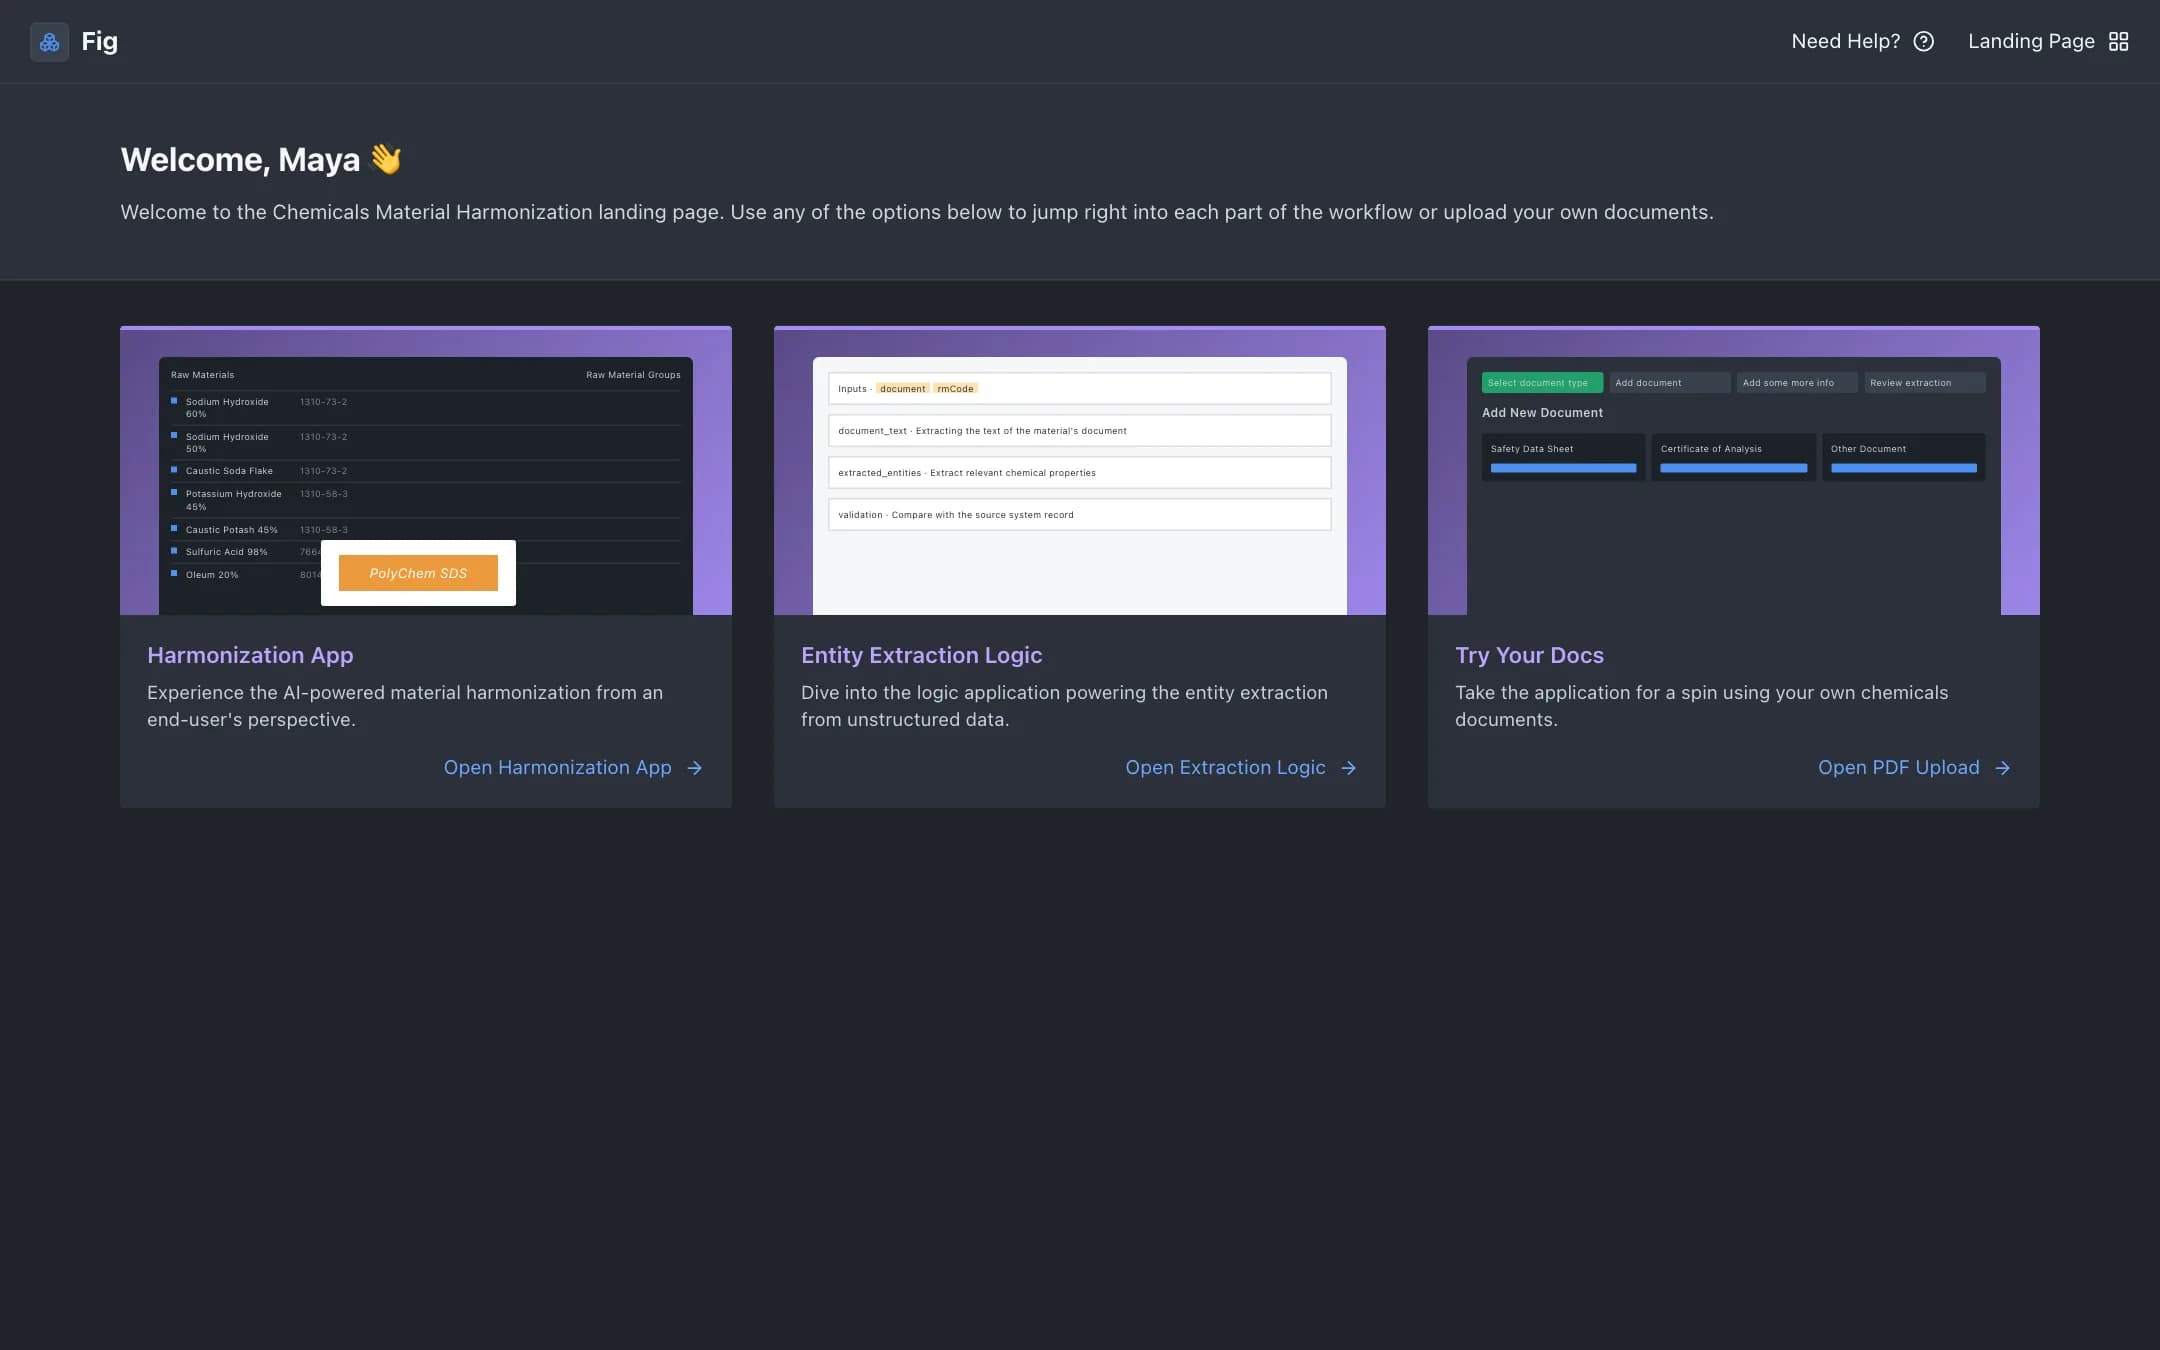
Material harmonization
Raw materials from several ERPs enriched with properties extracted from safety data sheets and certificates of analysis, grouped into harmonized materials with AI suggestions, so a bill of materials can name an alternative supplier.
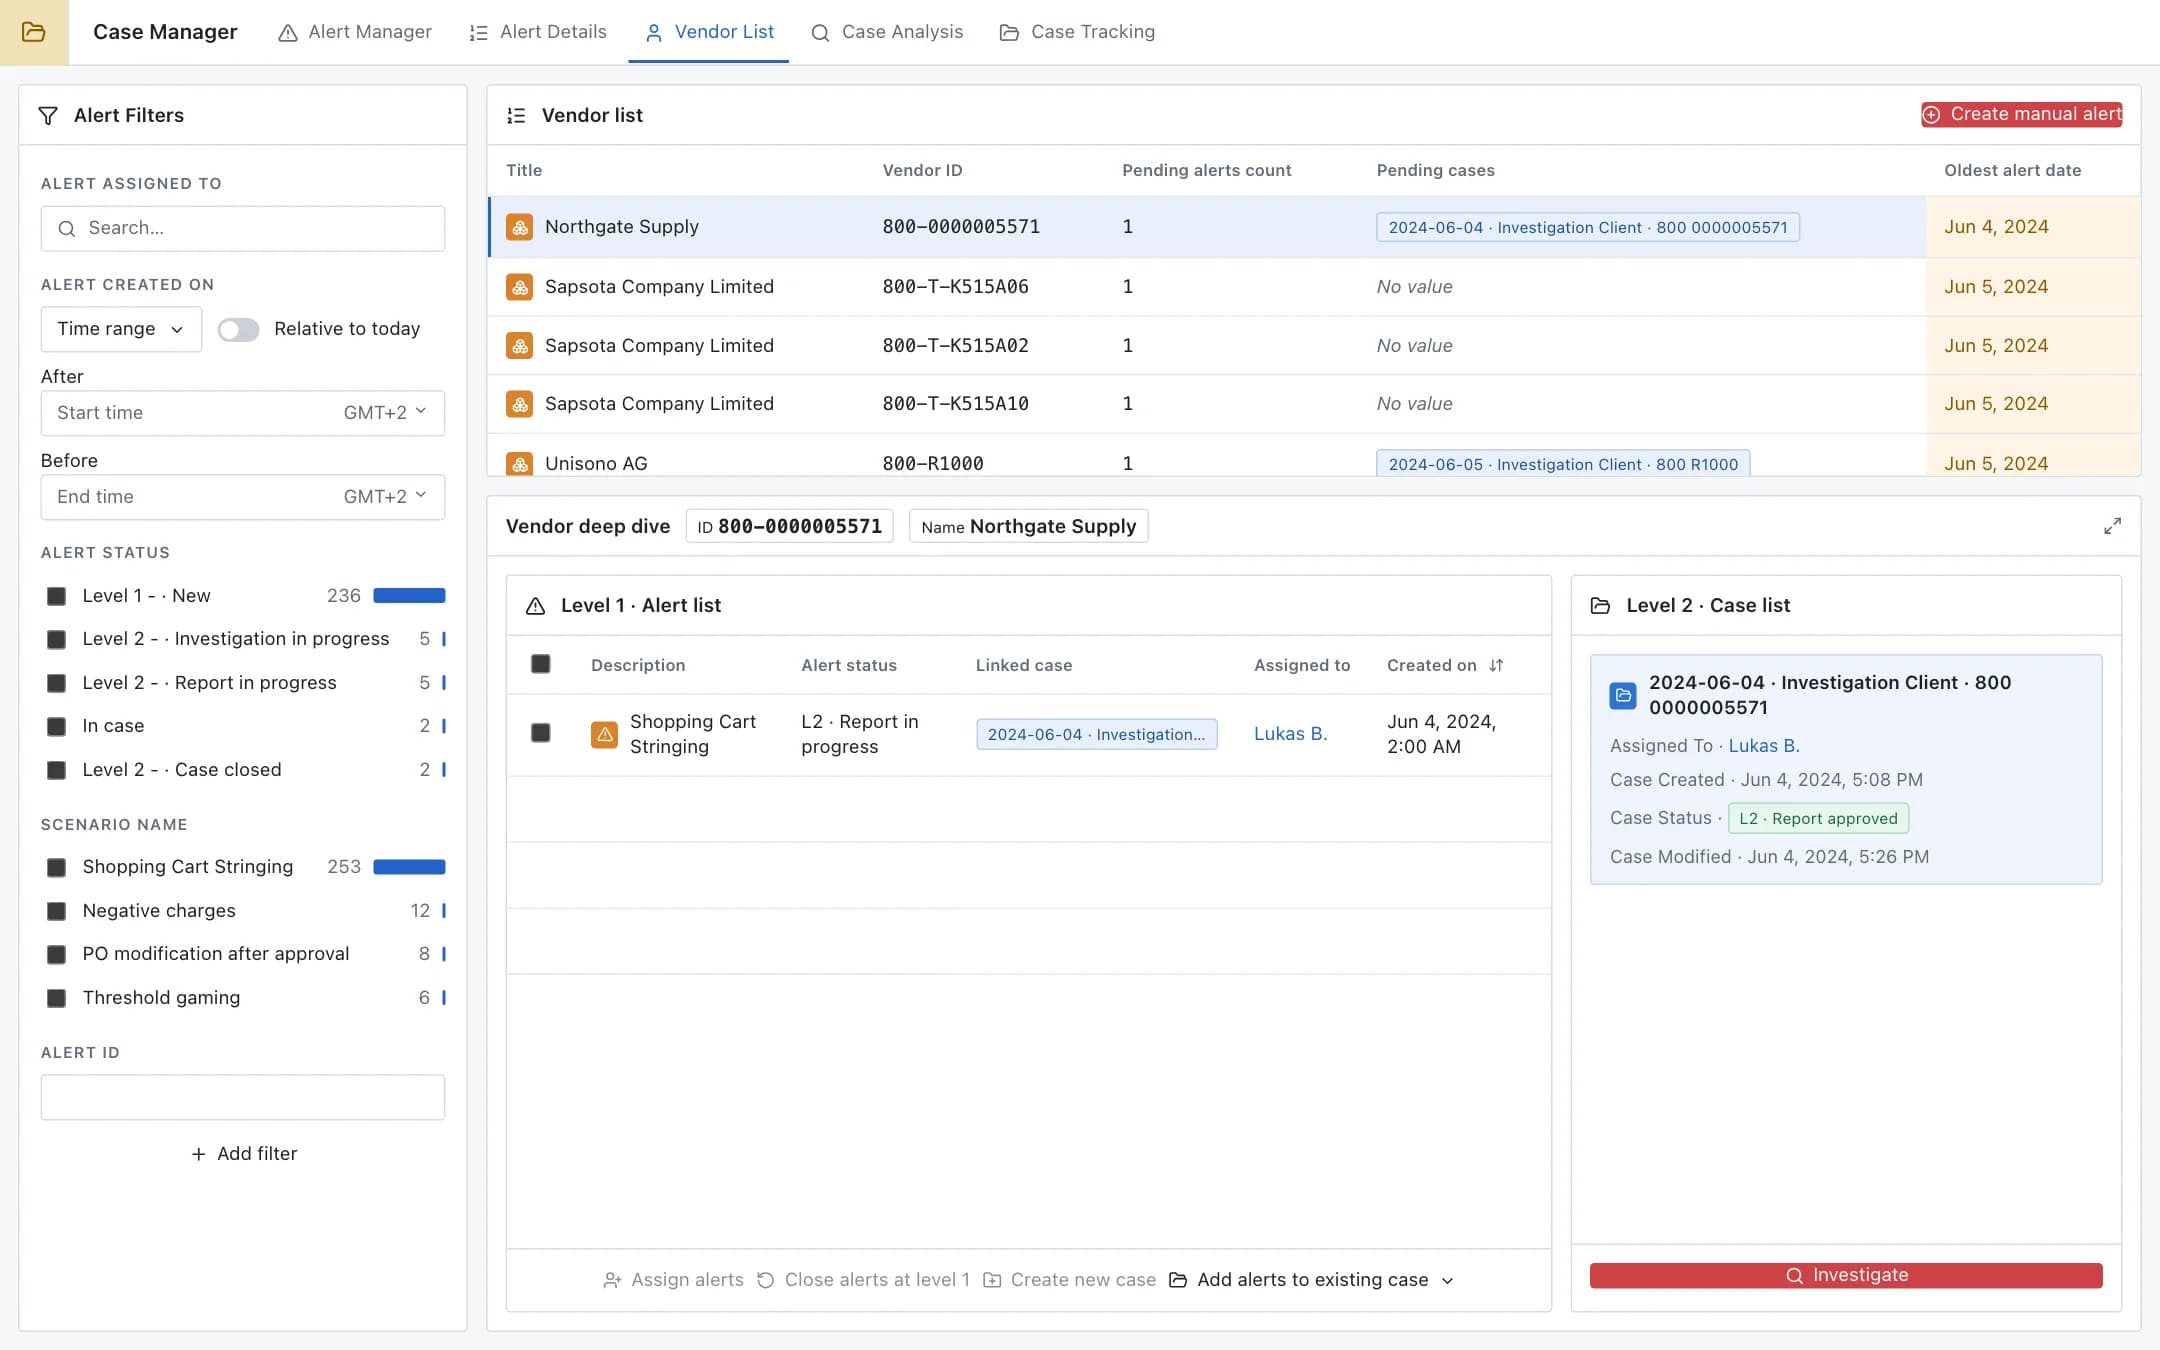
Procurement fraud detection
Purchase orders, invoices, vendors and bids scanned by detection rules for shopping cart stringing, PO modification after approval and threshold gaming; alerts triaged per vendor, escalated into cases, investigated, and fed back into the rules.
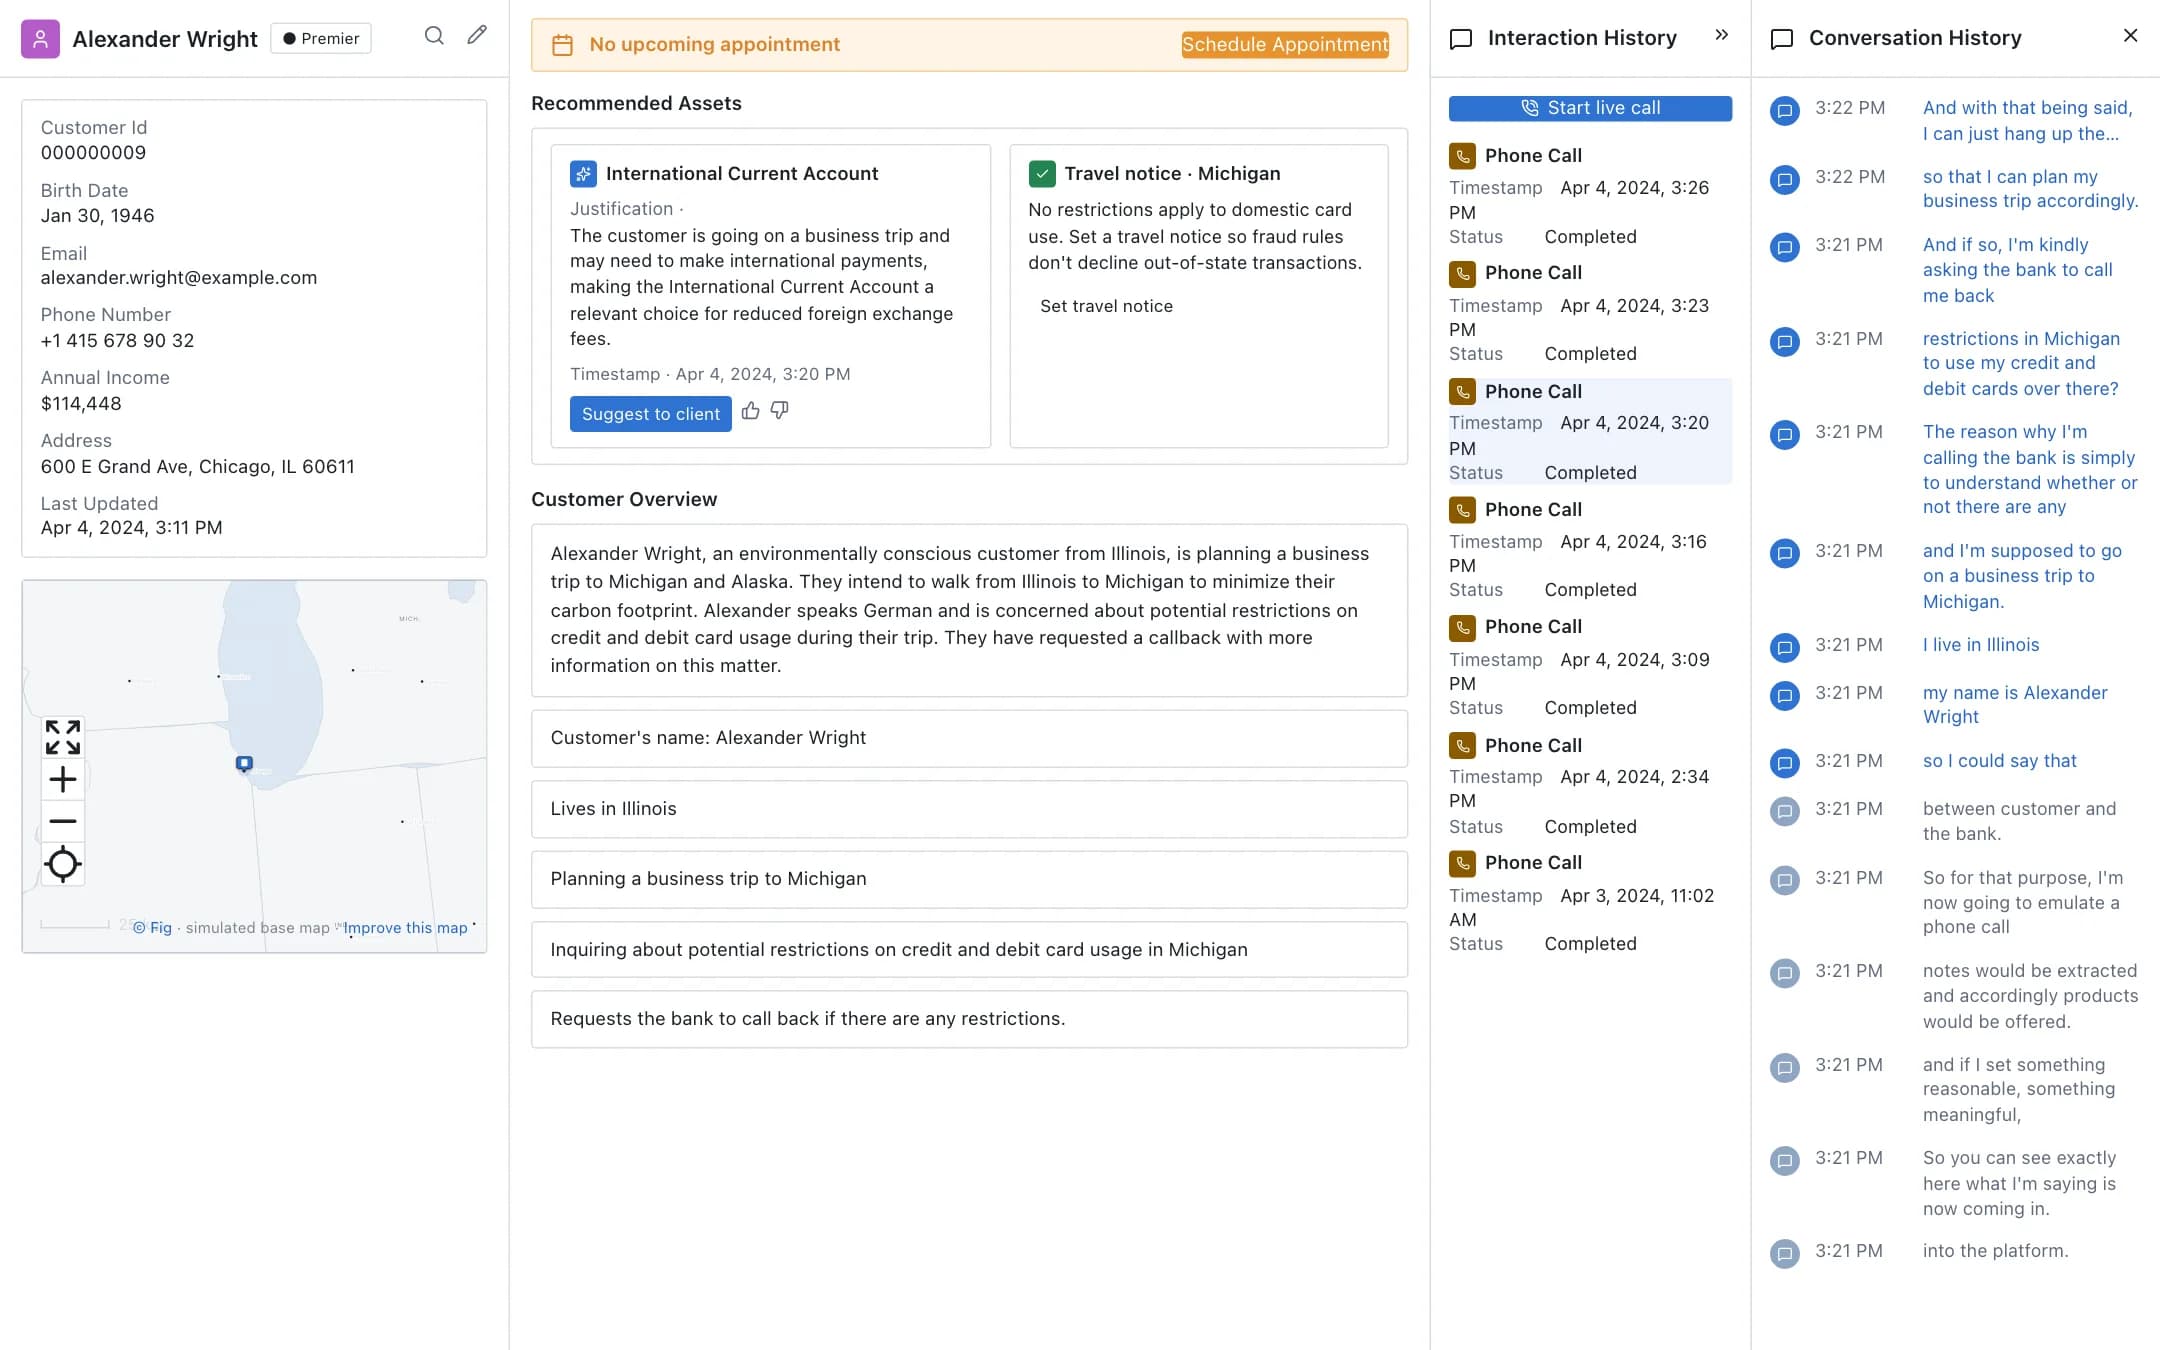
Real-time customer intelligence
The customer's record, the live call transcribed as it happens, facts and intent extracted from it, a recommended product with its justification, the interaction history and a callback booked, all on the relationship manager's screen during the call.